Migrate in one line
Point any OpenAI-compatible client to SovInfra. Call a model directly or use SovAPI routing without a custom integration.
 SOVINFRAPrivate modeless inference · EU-hosted.
European AI inference
Fast, cost-efficient inference for AI agents, voice AI and business automation. Choose your model or deploy dedicated European capacity at serverless pricing. Pay per token.
No credit card required.
14-day trial · 100 million tokens per day · Up to 2 requests processed concurrently per account · Up to 160,000 input tokens per Qwen or Gemma request.
First-token target under 120 ms, excluding queue time · Redundant hosting designed for 99.95% availability
Built for production AI
Point any OpenAI-compatible client to SovInfra. Call a model directly or use SovAPI routing without a custom integration.
Gemma 4 31B, Qwen 3.8-27B, Whisper, BGE-M3 and Kokoro are tested, monitored and served by SovInfra. Specialized open-weight models can be deployed for your workload.
Run your own prompt on SovInfra and see TTFT and generation speed without creating an account.
No intermediary, no data retention and no training on customer data. Built for repetitive, context-heavy agent loops.
Priority and high-performance capacity built around your workload. OpenAI-compatible API.
Answer five questions about your use case and production profile.
Use your free token allowance to measure performance on your own workload.
We size the deployment around your model, cache usage, context length, and concurrent requests. We provide a written proposal specifying the GPU capacity reserved for your environment.
Automatic routing
Let SovAPI choose"model": "sovapi"Direct model call
Gemma 4 31B"model": "gemma-4-31b"Direct model call
Qwen 3.8-27B"model": "qwen3.8-27b"Faster
At 256 output tokens, the Qwen comparison estimates 1.13 s on Sovinfra and 11.23 s on Prime Intellect (≈9.9×).
137 ms first token · 255.62 tokens/s
120 ms first token · 100 tokens/s · Dedicated thresholds, excluding queue time
723 ms first token · 128.47 tokens/s
400 ms first token · 87 tokens/s · OpenRouter
850 ms first token · 71 tokens/s · OpenRouter
880 ms first token · 57 tokens/s · OpenRouter
1654 ms first token · 63.78 tokens/s
330 ms first token · 26 tokens/s · OpenRouter
1420 ms first token · 26 tokens/s · OpenRouter
Estimates at equal output length, combining first-token latency and generation. Sovinfra Arena and OpenRouter observations were taken under different conditions. On playback, each row starts at its first token, then advances at its generation rate. Playback time is scaled for display.
Prime’s DeepSeek V4.1 Flash 1017 observation of 99 tokens/s needs a paired first-token measurement before a total can be calculated.
Cheaper
$3 on the Sovinfra Shared API plan vs. $4,140.63 for Claude Opus 4.8 via Anthropic on OpenRouter, per billion total tokens.
At a 15:1 input-to-output ratio with 50% of input cached, the comparison basket contains 1B input and 66.67M output tokens. It costs $4,416.67 on OpenRouter. That effective rate assumes 4B total tokens are used on the $12/month plan. If the quota is weekly, this means using 1B in each of four weeks. Figures exclude tax.
Sovinfra.Cost
Same basket in both views · 1B input tokens · ~66.67M output tokens · 15:1 input-to-output ratio
Share of input tokens read from cache
| Provider / model Rates in USD per million tokens | Price / cost |
|---|---|
| Sovinfra · Qwen / Gemma$12/month · $3 per billion tokens at full usageShared API · performance varies with load. Dedicated thresholds apply to the agreed configuration and workload. | $3.00per 1B tokens |
| Prime · Gemma 4 31BInput $0.2 · Cache $0.1 · Output $0.335OpenRouter · 0.33–0.47 s latency · 19–26 tok/s | $172.33 |
| Prime · DeepSeek V4.1 Flash 1017Input $0.0437 · Cache $0.0024 · Output $0.7OpenRouter · 93 tok/s · latency unavailable in this reading | $69.72 |
| Prime · DeepSeek V4 FlashInput $0.44 · Cache $0.014 · Output $1.32OpenRouter · 0731 variant · 0.88 s latency · 57 tok/s | $315.00 |
| Prime · Qwen 3.8 27BInput $0.45 · Cache $0.05 · Output $3.2OpenRouter · 0.93–1.42 s latency · 11–26 tok/s | $463.33 |
| Prime · Claude Haiku 4.5Input $1 · Cache uses input rate · Output $5No Prime-specific OpenRouter measurement found. | $1,333.33 |
| Prime · Claude Sonnet 5Input $2 · Cache uses input rate · Output $10No Prime-specific OpenRouter measurement found. | $2,666.67 |
| Prime · Claude Opus 4.8Input $5 · Cache uses input rate · Output $25No Prime-specific OpenRouter measurement found. | $6,666.67 |
| Anthropic via OpenRouter · Claude Haiku 4.5Input $1 · Cache $0.1 · Output $5OpenRouter · 0.40 s latency · 87 tok/s | $883.33 |
| Anthropic via OpenRouter · Claude Sonnet 5Input $2 · Cache $0.2 · Output $10OpenRouter · 0.95 s latency · 76 tok/s | $1,766.67 |
| Anthropic via OpenRouter · Claude Opus 4.8Input $5 · Cache $0.5 · Output $25OpenRouter · 0.85 s latency · 71 tok/s | $4,416.67 |
Basket estimates use the same token volumes and exclude taxes. The Sovinfra Shared Plan row shows its effective rate per billion total tokens at full use of the $12 monthly plan. Per-Token Pricing compares reference rates without subscription fees. Standard input rates apply where no cached rate is listed. Prime rates from 14 November 2026 screenshots. Anthropic rates are those listed by OpenRouter for the Anthropic endpoints. OpenRouter performance figures are observations for the linked endpoints and vary over time. OpenRouter observations and Sovinfra Dedicated guarantees use different conditions.
Workflow intelligence
We had to extend the x-axis.
At the same Qwen 3.8-27B reference score, the estimated cost per task is ≈$0.0065 on Shared Plan at full usage, ≈$0.21 at Sovinfra per-token rates and ≈$0.937 on Prime Intellect.
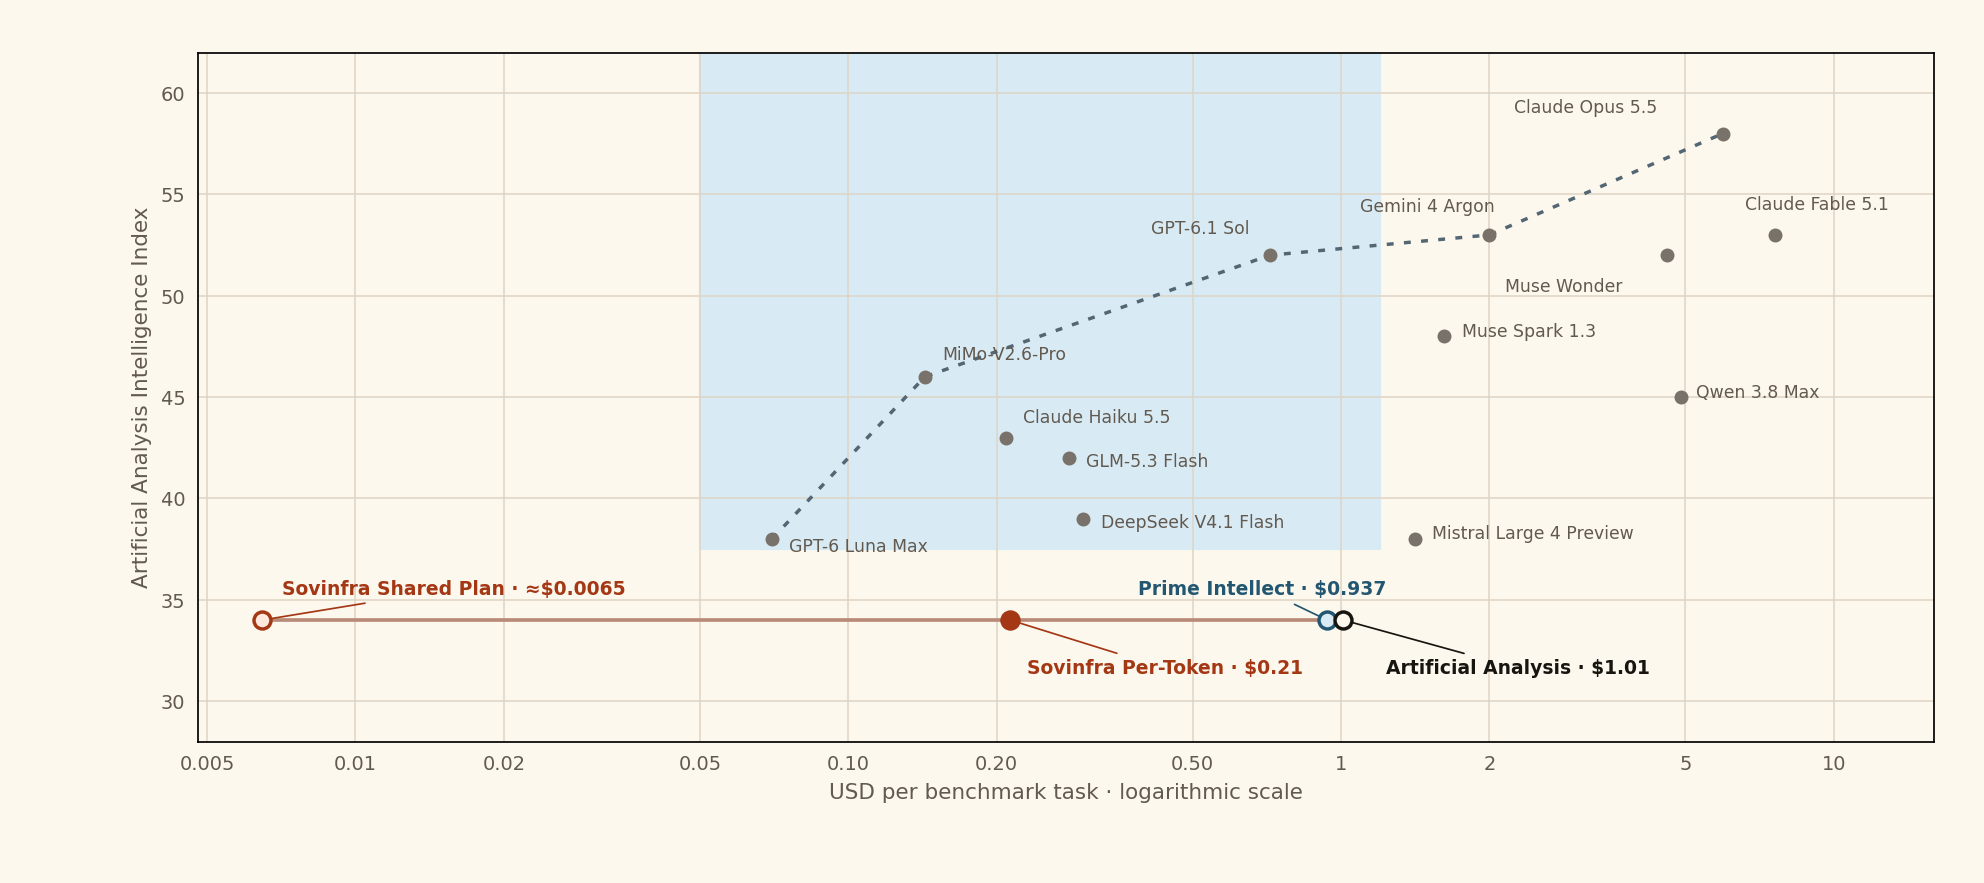
Results published by the model developers, according to their evaluation protocols.
Try Sovinfra$14.40 USD per month with 20% French VAT, when applicable. Your total depends on your billing location and is shown before payment.
For your agents, tools, and applications.
< 120 ms time to first token, excluding queue time
> 100 tokens/s generation speed per request
Throughput and latency vary with shared load. Individual performance is not guaranteed.
Shared API · Input and output beyond the shared weekly allowance.
| Uncached input | $0.12 |
|---|---|
| Cached input | $0.04 |
| Output | $0.38 |
14-day trial · 100 million tokens per day · Up to 2 concurrent requests processed per account.
Up to 160,000 input tokens per Qwen or Gemma request.
DEDICATED API
Per-token billing
For production applications that require reserved GPU capacity.
Standard guarantees apply to the agreed configuration and workload.
Tell us about your workload →Qwen3.8-27B · FP8 on H200.
Gemma 4 31B · FP8 with BF16 KV cache on H200.
Qwen and Gemma accept text and image inputs. Context window of 262,144 tokens.
No per-account limit on concurrent or queued requests.
Caching speeds up repeated requests and reduces costs beyond the allowance.
Your data is not used to train models. Requests and responses are not retained in logs.
Requests are processed on GPUs located in Europe with a named hosting provider.
Model versions and quantization are disclosed.
Usage dashboard and email support.
EU hosting · Your data is excluded from training · OpenAI-compatible API
Real-world applications
AI agents, CRM workflows, customer support and business process automation.
Extract, analyse and structure information from contracts, invoices, reports and business documents.
Production analytics, operational reporting, data processing and decision-support workflows.
Flexible model settings
Qwen 3.8-27B
Three reasoning levels are available: none, medium and xhigh. The default is none (reasoning disabled). For more demanding tasks, increase the reasoning level in your API request.
"reasoning_effort": "medium""reasoning_effort": "xhigh"Higher reasoning levels may increase token consumption and latency.
Gemma 4 31B
The default image-processing budget is 560. For complex invoices, receipts and visual documents, increase it to 1120 in your API request.
"mm_processor_kwargs": { "max_soft_tokens": 1120 }Higher image-processing budgets may increase token consumption and processing time.
Built for European workloads
All inference runs on European GPUs. No data leaves the EU.
No training on user data. End-to-end encryption. DPA available.
Requests are processed in the EU and are not retained or used to train models.
Our infrastructure stack is open for inspection on Codeberg. Full transparency on security and routing.